Quick Answer
NVIDIA Nemotron is the most powerful open model yet, Nemotron 3 Ultra, packs 550 billion parameters (55 billion active) and launched on June 4, 2026. Built for long-running AI agents, it supports a 1-million-token context window and currently scores highest among all open-weight models on the Artificial Analysis Intelligence Index.
What Is Nemotron 3 Ultra?
Nvidia Nemotron ultra 3 is a flagship open-weight AI model, built for agentic workflows tasks where an AI works through dozens or hundreds of steps without losing track. Think coding agents, research assistants, and enterprise automation that runs unsupervised for long stretches.
Part of the Nemotron 3 Family
Nemotron 3 Ultra sits at the top of a three-tier lineup:
- Nano: lightweight, built for on-device tasks
- Super: mid-size, balances speed and capability
- Ultra: the flagship, built for the hardest reasoning tasks
Fully Open, Not Closed
Unlike GPT or Claude, Nemotron 3 Ultra’s weights, training data, and full training recipes are public. Anyone can download, fine-tune, or deploy it.
Key Specs
| Spec | Detail |
|---|---|
| Total parameters | 550 billion |
| Active parameters | 55 billion per token |
| Architecture | Hybrid Mamba-Transformer MoE |
| Context window | Up to 1 million tokens |
| Quantization | NVFP4 (4-bit) |
| Intelligence Index | 48 (highest open model) |
| Release date | June 4, 2026 |
Why the Architecture Matters
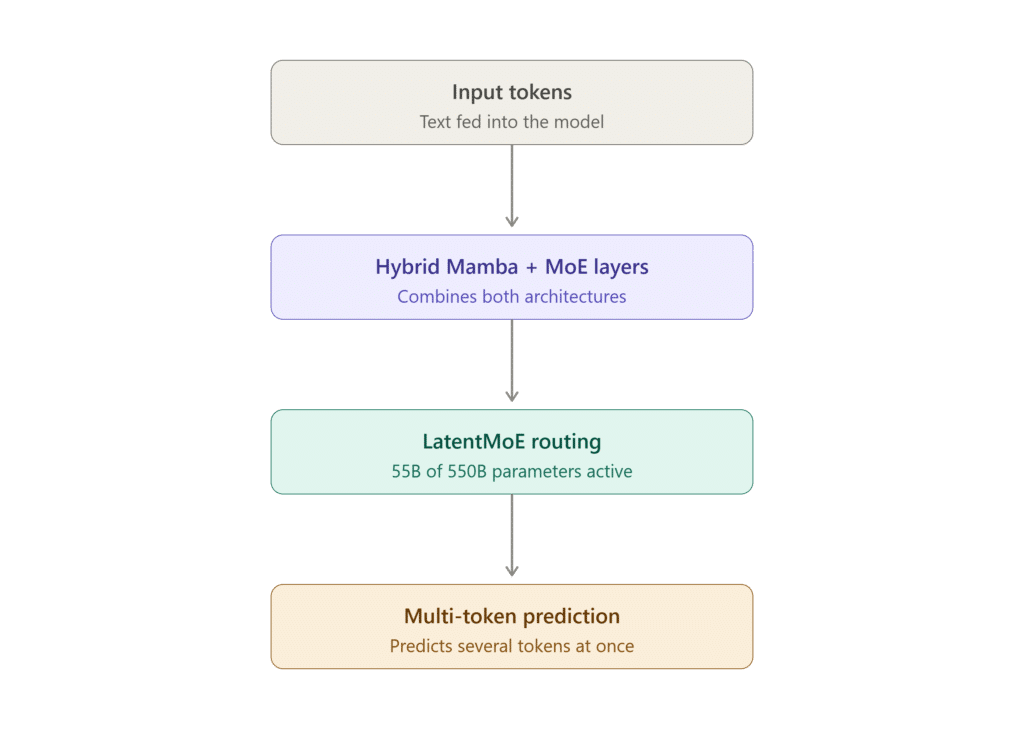
A Hybrid Design
Nemotron 3 Ultra doesn’t use a standard Transformer. It combines Mamba layers with Mixture-of-Experts (MoE) routing, so only a fraction of its parameters activate per task.
Built-In Speed Boosters
- LatentMoE: smarter routing between internal “experts” for better accuracy
- Multi-Token Prediction: generates several tokens per step, speeding up long agent sessions
- NVFP4 pretraining: a 4-bit format that shrinks memory use and speeds up inference
Why It’s Efficient
Only 55 billion of the 550 billion parameters activate at once. That means frontier-level reasoning without the cost of running a dense model that size.
How Fast and Accurate Is It?
Speed
Nvidia Nemotron reports up to 5.9x higher throughput than comparable open models on long input/output tasks.
Coding Performance
On SWE-bench and Terminal-Bench 2.0, it completes tasks using roughly 30% fewer tokens than similar models lowering the cost of long coding sessions.
Benchmark Score
It scores 48 on the Artificial Analysis Intelligence Index, ahead of Nemotron 3 Super (36) and GPT-OSS 120B (33) the top score among open-weight models.
How NVIDIA Nemotron 3 Ultra Was Trained
Multi-Teacher On-Policy Distillation
NVIDIA Nemotron 3 Ultra wasn’t just pretrained and released — it went through a multi-stage post-training pipeline built to sharpen its agentic reasoning. Its post-training data has a cutoff of May 2026, and the model was refined using Multi-Teacher On-Policy Distillation (MOPD), meaning NVIDIA Nemotron 3 Ultra learned from dense feedback provided by more than ten domain-specific teacher models rather than a single training signal.
Pretraining Scale
The base version of NVIDIA Nemotron 3 Ultra was pretrained on roughly 20 trillion tokens, drawing from crawled and synthetic data across code, math, science, and general knowledge. NVIDIA also released dedicated pretraining datasets alongside the model, including a fresh code dataset pulled from GitHub through September 2025, giving developers visibility into exactly what the Nemotron 3 Ultra model learned from.
Fully Open Training Recipes
What sets NVIDIA Nemotron 3 Ultra apart from most frontier models is that NVIDIA published the entire recipe: weights, reward models, quantized variants, and training methodology are all public. That transparency lets researchers reproduce or build on the NVIDIA Nemotron 3 Ultra training process instead of treating it as a black box.
Real-World Use Cases for NVIDIA Nemotron 3 Ultra
Coding Agents
NVIDIA Nemotron 3 Ultra is tuned for coding harnesses that need to keep working through a task rather than stopping after one response. Because it completes benchmarks like SWE-bench using fewer tokens per run, NVIDIA Nemotron 3 Ultra lowers the practical cost of running an autonomous coding agent across an entire session.
Deep Research and Document Analysis
With a 1-million-token context window, the NVIDIA Nemotron 3 Ultra model can hold an entire research trail, codebase, or document set in memory at once. That makes it well suited to synthesizing findings across hundreds of sources without losing earlier context.
Enterprise Orchestration
NVIDIA Nemotron 3 Ultra is also built for orchestration — coordinating multiple tool calls and sub-tasks inside a larger workflow. NVIDIA specifically points to use cases like verifying chip designs across thousands of constraints, which requires the kind of sustained, multi-step reasoning NVIDIA Nemotron 3 Ultra was trained for.
Limitations to Keep in Mind
Despite its scale, NVIDIA Nemotron 3 Ultra isn’t a universal upgrade over every model on the market. It’s optimized specifically for agentic and reasoning-heavy tasks rather than casual conversation, and running it at full precision demands significant GPU memory — the BF16 version is far too large for most local setups. Businesses evaluating NVIDIA Nemotron 3 Ultra for production use should weigh its hardware requirements against the NVFP4-quantized version, which trades some memory footprint for slightly reduced precision.
What Can You Actually Do With It?
Because it’s fully open, Nemotron 3 Ultra can be:
- Run locally or on private infrastructure
- Fine-tuned for a specific industry
- Deployed inside coding agents or support systems without a closed API
- Accessed through platforms like Hugging Face, Ollama, and OpenRouter
Running the full model still needs serious GPU power, which is why a smaller NVFP4-quantized version exists for lighter setups.
Is Nemotron 3 Ultra free to use?
Yes, it’s open-weight, so the model is publicly downloadable. Some hosted versions are also free, though self-hosting needs strong GPU resources.
How does it compare to GPT or Claude?
It’s optimized for agentic, long-running tasks rather than general chat, and it’s currently the top open-weight model though some closed frontier models still lead on certain benchmarks.
What is NVFP4?
Nvidia’s 4-bit floating-point format that compresses the model, cutting memory use and boosting speed with minimal accuracy loss.
Can I run it on my own computer?
The full model needs serious GPU memory, but quantized versions, including a 1-bit build, are available for smaller local setups.
What is it best used for?
Long-running AI agents coding assistants, research tools, and multi-step enterprise workflows rather than short chat conversations.
The Bottom Line
Nvidia Nemotron 3 Ultra is a biggest bet yet on open, agent-ready AI. For developers and businesses comparing open-weight models in 2026, it’s currently the most powerful US-built option available.
Curious how AI is changing search and SEO? LayersPilot can help you adapt!

I’ve spent over 8 years working across SEO, WordPress development, Laravel, and UI/UX design, helping businesses improve their websites, search visibility, and overall digital presence. My experience includes on-page and off-page SEO, technical optimization, content strategy, WordPress development, and user-focused design for a range of clients and businesses.
Over the years, I’ve worked with teams including Skyray Ventures, Dotrefl, and ESPA Builders, combining technical development with digital marketing to deliver practical, measurable results.
I’m currently developing Laravel-based web applications at Princess Tourism while also growing LayersPilot, a digital services platform focused on SEO, web design and development, and website customer care.
One project I’m particularly proud of is Catch Head, an AI-powered lead generation platform developed by my team and presented at the Microsoft Imagine Cup at the national level.
I’m especially interested in SEO, Generative AI, prompt engineering, and AI-driven content strategy, and I enjoy connecting with businesses and professionals looking to strengthen their online presence through technology and search.